 flemming-it
f1652cce62
Fetch one German federal law from gesetze-im-internet.de (BMJ) by its
site slug, unpack the BMJ norm XML from the site's xml.zip and return
it content-addressed (SHA-256) plus the BMJ builddate, so a flow's
audit trail pins the exact Gesetzesstand it processed.

- xml.zip unpack picks the largest XML entry (norm body)
- lying ZIP size header rejected instead of silently truncated
  (audit integrity); 64 MB unpack cap, 96 MB download cap
- net permission pinned to www.gesetze-im-internet.de; no auth
- 11 unit tests (no network), wasm32-wasip2 build green

Signed-off-by: flemming-it <sf@flemming.it>
1.9 KiB
source.bundesrecht
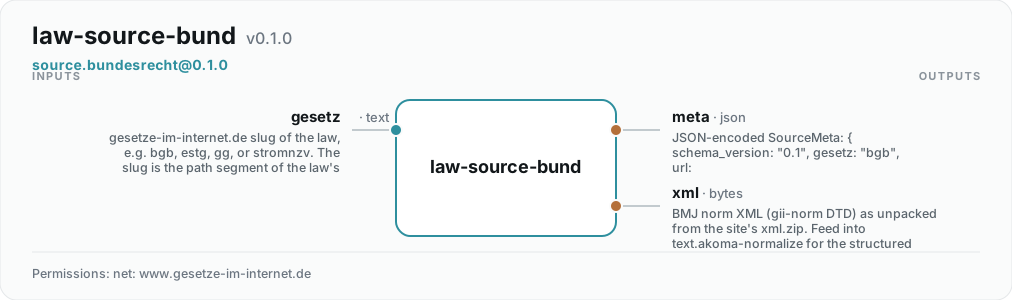
Fetch German federal law from gesetze-im-internet.de by slug
What it does
Resolves a gesetze-im-internet.de slug (e.g. bgb, estg, gg,
stromnzv) against the public BMJ publication site, downloads the
law's xml.zip, unpacks the BMJ norm XML (gii-norm DTD) and returns
it plus a metadata record. The unpacked bytes are content-addressed
(SHA-256), so the flow's audit trail pins the exact Gesetzesstand
that was processed.
Unlike EUR-Lex, gesetze-im-internet serves only the CURRENT
consolidated state — there is no URL for an older version. The
SHA-256 (plus the BMJ builddate from the XML header) is what makes
a later re-fetch comparable: a change upstream becomes visible
instead of silent.
Public BMJ data only; network permission is pinned to
www.gesetze-im-internet.de.
How to use
steps:
  - id: fetch
    use: source.bundesrecht@^0
    with:
      gesetz: stromnzv

  - id: normalize
    use: text.akoma-normalize@^0
    with:
      content: $fetch.xml
The slug is the path segment of the law's page on
gesetze-im-internet.de: https://www.gesetze-im-internet.de/<slug>/.
Outputs
xml— the BMJ norm XML as unpacked from the site's archive. Feed intotext.akoma-normalizefor the structured Akoma-Ntoso-aligned representation (its v0.1 BMJ adapter handles this format natively).meta— JSON SourceMeta:gesetz,url,source_sha256,byte_len, andbuilddatewhen the XML header carries one.
Errors
- Unknown slug → clear invalid-input error naming the checked URL.
- Non-ZIP or XML-less download, HTML error pages → internal error with the reason; nothing HTML-shaped is ever passed downstream.